Evaluating an HFSS agent: benchmarks and an honest loss
An agent that drives Ansys HFSS can look convincing and still build the wrong model. I built the benchmarks that tell the difference, graded against gold AEDT reference projects.
The benchmarks
- An atomic prompt suite, each prompt a single HFSS task, graded against a gold reference project.
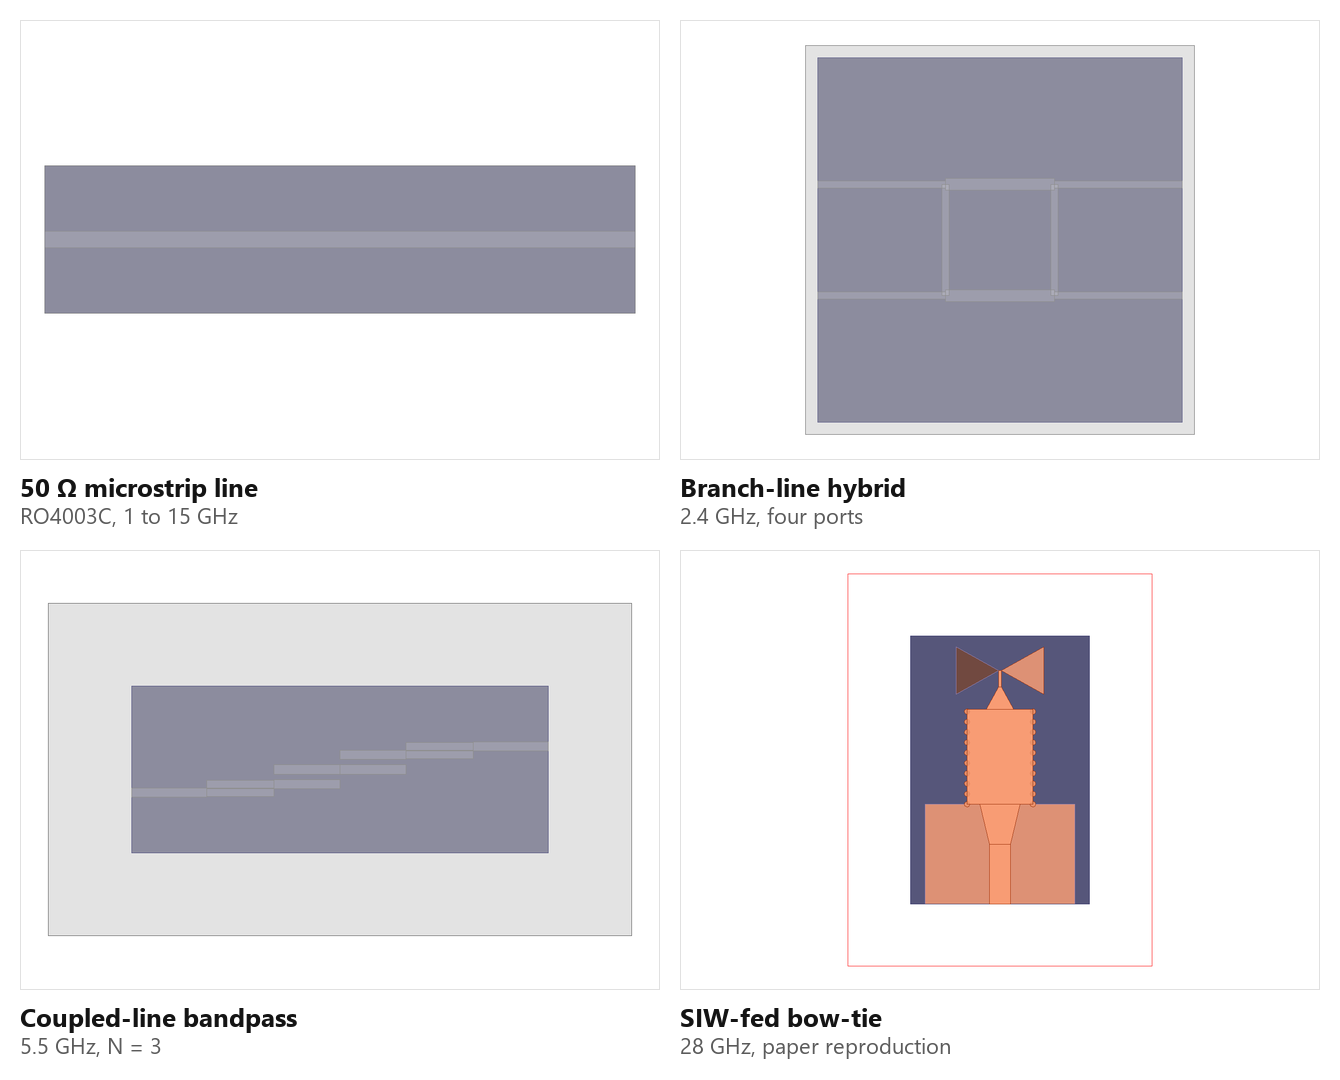
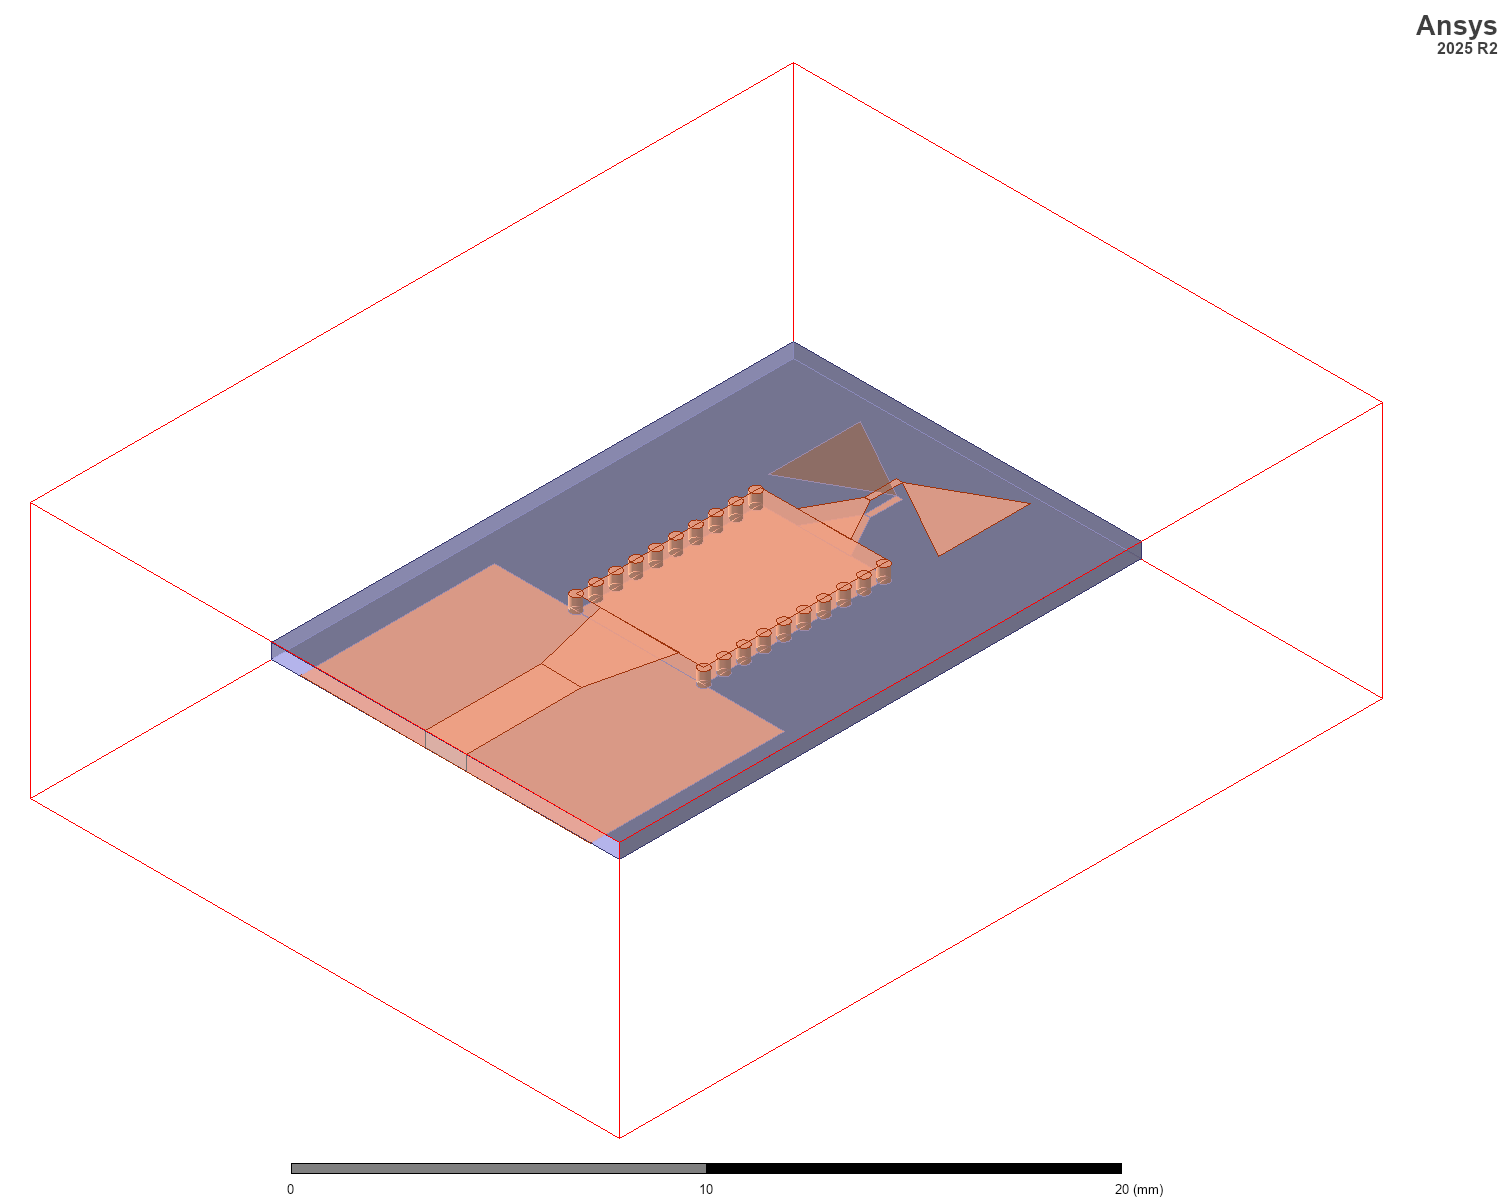
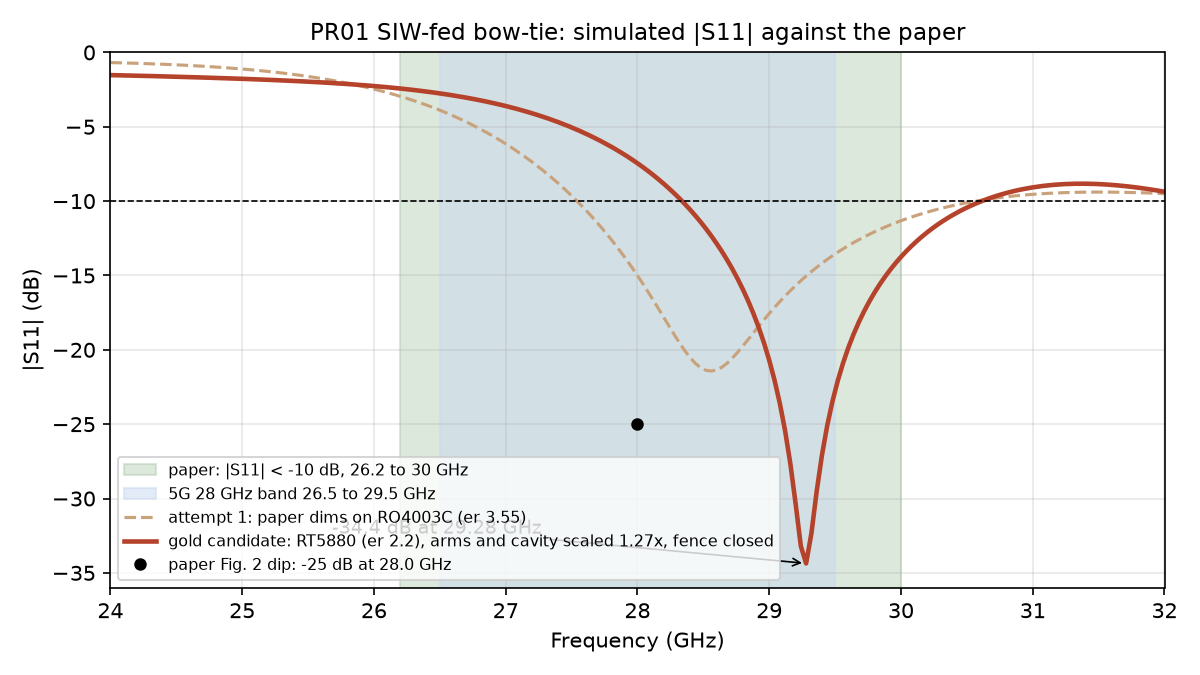
- Design-level gold benchmarks: a 50 Ω line, a modify-in-place edit with protected invariants, a 2.4 GHz branch-line hybrid, a coupled-line bandpass filter and a 28 GHz antenna rebuilt from a published paper. Structure is checked from the saved project and RF performance from the exported Touchstone.
An honest loss: the A/B race
Two agents on the same model had four hours to design a 1:6 power divider from 2 to 18 GHz, graded only on the Touchstone file each delivered. Agent B also had a corpus of past design lessons.
Agent A won the graded metric, even though B met more of the spec’s gates and cost less. B got stuck on an amplitude tilt and kept a mesh that made its solves much slower. Neither agent was told how it would be graded, and a rerun should tell them.